
Developer-tool opportunities start where production confidence breaks
The map points to data reliability, operational readiness, and model hardening rather than another undifferentiated coding assistant.
Introduction
Developers adopt tools that remove uncertainty from a real delivery path. The current opportunity is strongest where a team cannot trust its data, reproduce a failure, meet a reliability promise, or move an ML prototype into controlled production.
The August 24 Trend Seeker snapshot connects 3,027 ideas to 59,222 distinct signals in this category. That is not a list of businesses to copy. It is evidence about work people fund, problems operators describe, and product gaps founders can investigate.
What the map says now
Developer tools draw 41,285 distinct signals from job ads, 5,051 from podcasts, 4,521 from Reddit, 4,046 from app reviews, 3,523 from Product Hunt, and 684 from Google Trends. Hiring remains the clearest evidence of funded infrastructure work; the other sources expose setup, reliability, and switching friction.
| Measure | Current snapshot | How to read it |
|---|---|---|
| Ideas in this category lens | 3,027 | Ideas can appear in more than one category. |
| Distinct supporting signals | 59,222 | Deduplicated within each source. |
| Fresh signals, 7 days | 1,828 | Recent evidence, not estimated search volume. |
| Fresh signals, 30 days | 8,614 | A check on whether the problem is still active. |
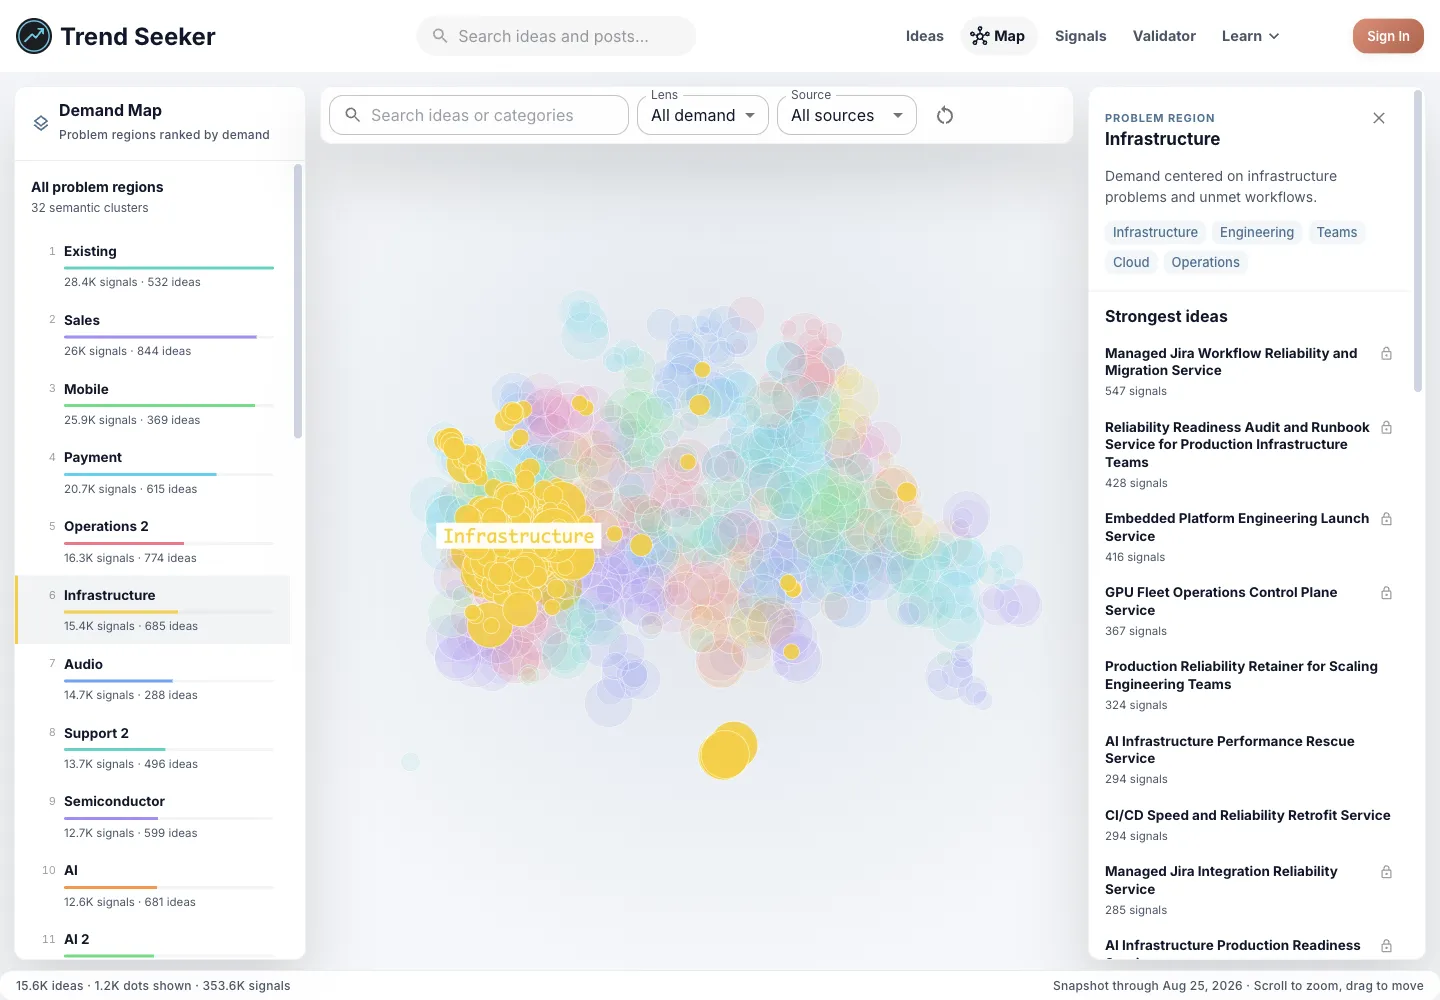
| Infrastructure Gaps | 500 related ideas | The most useful map cluster for this editorial angle. |
The 30-day distinct-signal window changed from 32,339 in the July 21 review to 8,614 now. This compares recent evidence windows, not total market size, search impressions, or purchase intent.
The selected cluster below is one way into the evidence, not the whole category. Open the live Infrastructure Gaps view to inspect the current ideas and signals.
Where the opportunities are
1. Data contracts need operational ownership
Pipelines fail between teams, not only inside code. A useful product traces a broken business metric to a schema, job, owner, and recovery action instead of adding another passive dashboard.
A useful first wedge: Start with one warehouse and one critical reporting path, including a clear incident handoff.
2. Reliability readiness is sellable before observability software
Teams often have metrics but lack tested runbooks, acceptance standards, and failover evidence. DORA's delivery metrics help frame outcomes, but a founder still needs to connect them to a narrow operating change.
A useful first wedge: Sell a readiness audit for one service, then automate evidence collection and runbook testing.
3. Reproduction remains an expensive bottleneck
Logs, versions, flags, data, and environment state are scattered when a production failure reaches engineering. Tools that package a trustworthy reproduction can shorten the highest-cost part of incident and support work.
A useful first wedge: Capture one class of failure from one stack and produce a replayable case with sensitive data removed.
4. ML platforms need cost and rollback controls
Training and serving workflows become operational systems with dependencies, budgets, regressions, and recovery needs. A focused hardening layer can win before a team is ready to replace its platform.
A useful first wedge: Add regression, cost, and rollback checks to one existing model-delivery workflow.
Three concrete expressions of these patterns are Data Pipeline Reliability Studio for Growing Operations Teams, Reliability Readiness Audit and Runbook Service, Production ML Pipeline Hardening Service. Their cards remain visible below while you read so you can move from the editorial argument to the underlying idea evidence.
Ready to explore developer tools business ideas?
Explore developer tools opportunities backed by current market evidence.
This Developer Tools snapshot contains
+3,027ideas
and
+59,222signals


What to sell first
| Opportunity | Sell first | Avoid building first |
|---|---|---|
| Data reliability | Critical-pipeline reliability sprint | New data platform |
| SRE | Runbook and failover audit | Observability suite |
| Debugging | Reproduction bundle for one stack | Universal debugger |
| MLOps | Hardening and rollback package | End-to-end ML platform |
Where founders get it wrong
Developer enthusiasm does not guarantee organizational purchasing. A tool can be loved by individual engineers and still lose to security review, platform standardization, integration cost, or an incumbent bundled into the cloud bill.
The map helps discover a problem and find language customers use. It does not prove market size, willingness to switch, purchasing authority, or a durable distribution advantage. Read the job-ad signal guide when the evidence is hiring-heavy, then use the startup validation guide before committing to a build.
A 30-day validation plan
- Choose one costly event. Use a failed deployment, broken data report, long incident, or model rollback where the team can estimate delay and engineering hours.
- Interview ten people around that event. Include the operator doing the work, the manager accountable for the outcome, and someone involved in purchasing.
- Collect the current artifacts. Ask for the spreadsheet, ticket queue, report, checklist, or handoff that exposes the real workflow.
- Sell a fixed outcome. Define the input, delivery window, acceptance test, and price before automating the work.
- Productize repeated steps. Build software only after several customers need the same decision, evidence, or handoff.
Methodology
This edition uses the Demand Map snapshot generated August 24, 2026, with source data through August 24, 2026. Trend Seeker applied a stable editorial lens using terms such as developer tools, engineering platforms, data infrastructure, observability, SRE, debugging, CI/CD, and MLOps. One idea can belong to several categories, so category totals should not be added together. The full classified count is reported even when manual review finds cross-sector noise.
A distinct signal is deduplicated by source and logical signal key. It is not an idea, an idea-signal match, a source record, a Google Search Console impression or click, Google Trends relative interest, or a third-party search-volume estimate. We reviewed the leading ideas and the selected semantic region to form the editorial patterns above. The patterns overlap and should not be summed.
Frequently asked questions
What developer tool should I build?
Start with a production decision that is slow or unreliable, such as reproducing an incident, approving a release, or tracing a broken data metric.
How do developer tools make money?
The clearest budgets attach to reduced incident cost, faster delivery, compliance evidence, infrastructure savings, or fewer specialist hours.
How often is this developer-tools brief updated?
Trend Seeker reviews it every other week against the newest map and source evidence.


